Your AI pilot looks busy. Which result keeps it alive?
Set one measure, one owner and one stop rule. Then use Perplexity to check whether the evidence supports extending your AI pilot.
By Adrian Dunkley & the AI Boss team
Tool details and news reflect the 17 November 2026 edition.
Check the evidence before you extend an AI pilot
Select Copy prompt. Open Perplexity, select Search, then paste and submit the prompt.
Perplexity offers free standard search. It applies Pro Search automatically when your plan and quota allow. Access can vary by country. We found no confirmation for Jamaica in Perplexity’s published terms.
Practice case
Harbour View Guesthouse in Montego Bay says its AI reply assistant cut average response time from 18 to 11 minutes.
The team measured 40 enquiries over two weeks, including weekends, before the pilot.
It measured 14 enquiries over five weekdays during the pilot.
The team excluded three escalated cases from the pilot figures. It did not measure reply quality. Staff spent two hours correcting drafts.
What to do
Make a table with three columns: Item, Finding and Decision use. Cover response time, excluded cases, reply quality and time spent on corrections. Mark missing facts [MISSING]. Explain what the records support and what could have affected the comparison.
Recommend whether the operations manager should keep, fix or drop the pilot. Give one measure, one owner, one stop rule and one review date for a four-week test starting 17 November.
Use up to three official or research sources on comparing pilots. List each separately with its URL, publication date and the point it supports. Mark an unstated date [MISSING]. Use only the guesthouse records to assess the claim.
| Item | Finding | Decision use |
|---|---|---|
| Response time | The recorded average fell. The pilot covered weekdays only. | Compare the same kinds of days. |
| Excluded cases | The team left out three escalations. | Include every enquiry next time. |
| Reply quality | [MISSING] | Check replies before expanding. |
| Corrections | Staff spent two hours editing. | Count that time in the next trial. |
- Fix the pilotMeasure average response time across all enquiries.
- Name the ownerThe operations manager checks the log against the inbox.
- Set a stop rulePause if the log omits an inbox enquiry.
- Set a review dateDecide on 15 December.
Open each citation and check the point it supports. Keep the exclusions and missing quality data visible. Leave the cause of the recorded speed gain open.
Delegation · Description · Discernment · Diligence. Agree on the measure and record exceptions. Next lesson: repeat the check when the sample changes. AI Fluency course from Rick Dakan, Joseph Feller and Anthropic.
Compare models on the same file
Reddit pick. A developer reported on 16 November that Hydrogen spent two hours rebuilding Tabletop Tarot, their Minecraft data pack. They said a second model’s review found bugs. Give Hydrogen and your usual tool the same sample file. Check whether each output flags missing data.
AI news
The IDB models a 5.1% gain under broad AI adoption
The Inter-American Development Bank launched its report on 16 November.
The scenario puts economic output in Latin America and the Caribbean 5.1% higher after a decade if AI use spreads and productivity improves. The regional estimate depends on skills, data, infrastructure and stronger institutions.
Our takeaway. The regional estimate leaves your organisation’s return open. Choose one process and name who will compare its results before and during your pilot.
Google rolls out Gemini 4 Hydrogen
Google introduced Hydrogen on 12 November and updated its announcement on 16 November. The rollout covers the Gemini app, Search, developer tools and eligible business products.
In the free Gemini app, automatic model selection decides when to use Hydrogen. Paid products offer more controls.
Our takeaway. Try the guesthouse prompt if you can select Hydrogen. Check whether it keeps the three exclusions visible and marks reply quality [MISSING].
AI Boss Show & Tell
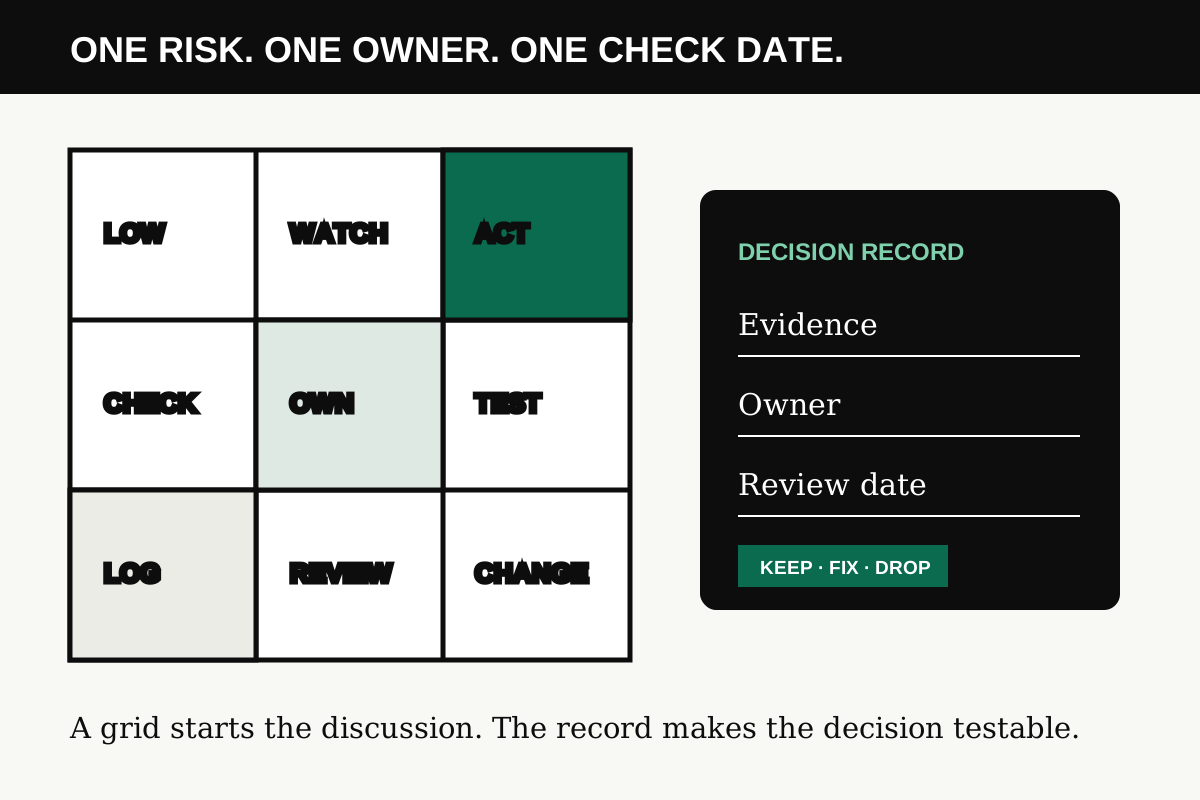
Teams can disagree on a risk rating before they agree on the evidence. On 17 November, AI Boss prepared the National Agentic Risk Matrix with nine practice scenarios. Pick one cell. Record the evidence for its position, name who owns the safeguard and say what would change the rating. The positions are editorial judgements for discussion. Base operational decisions on local evidence. Ask about adapting the method.
Set the target before the pilot starts
If you manage the pilot, open the North Star AI Canvas. Enter the 18-minute baseline and a practice target of 10 minutes. Add the owner, enquiry-to-reply process, tool cost in USD and a rule that staff check every draft.
Select Save One-Pager. In our 17 November test, the canvas saved the entries in the browser and opened a printable page. The page records your plan. Measure the actual result and take it to the 15 December review.
Sponsored · Our training
AI Officer board-level training
StarApple AI’s executive programme teaches teams to choose work, set rules, build an application and check results. Boards can use the same executive programme to decide what to fund, who oversees the work, who answers for the results and what measured value would justify more funding.
Further reading from the Caribbean AI Association
- Redesign work for AI maps a process, removes unnecessary steps and tracks service, time and workload.
- Which countries can reach the AI dividend? explains what the access score measures. Business benefits still need their own evidence.
- What job exposure measures separates tasks AI could affect from assumptions about hiring and job losses.
What evidence would make you stop the pilot?
Be the boss of AI